DCS redundancy is the planned use of independent standby controllers, servers, network paths, power sources, or other components so a defined failure can be managed without an unacceptable interruption to process operation. It is useful only when the failure domains are genuinely separated, switchover behavior is understood, and the design has been tested under realistic conditions. A redundant controller sharing one power supply, switch, cabinet, or maintenance dependency may still have a common point of failure.
Quick Answer: What Does DCS Redundancy Actually Protect?
DCS redundancy can protect selected process functions against a single component failure, such as a controller fault, server outage, network-path disturbance, or power-supply failure. The protection depends on the architecture: standby equipment must have compatible configuration, reliable health detection, a defined transfer mechanism, adequate capacity, and a safe post-failover state. Redundancy does not automatically protect against design errors, common-cause events, incorrect maintenance, software defects, unsafe bypasses, or loss of an entire facility.
Before approving a high availability DCS, engineers should map failure domains, define the required availability objective, distinguish control availability from safety integrity, and request commissioning evidence for normal operation, switchover, recovery, alarms, and degraded modes. A DCS availability and architecture review can provide the evidence needed to compare the installed design with the process risk and operating requirements.
What Is DCS Redundancy?
DCS redundancy is an architecture and lifecycle practice rather than a single hardware option. It may include duplicated controllers, paired communication modules, redundant servers, separate network paths, dual power supplies, independent cabinets, mirrored data services, or geographically separated recovery infrastructure. Each layer must have a defined role and failure response.
A redundant design should answer five questions: What failure is being covered? What remains common? How is the failure detected? What happens during switchover? How is the system returned to a healthy redundant state? If those answers are not documented and tested, the installation may offer only assumed redundancy.
Failure-Domain View of a Redundant DCS
| Source or Dependency | Connection or Affected Component |
|---|---|
| Process Controllers | Control Network A and Control Network B |
| Control Network A | Server or Operator Layer A |
| Control Network B | Server or Operator Layer B |
| Server or Operator Layer A | Operations and Engineering Users |
| Server or Operator Layer B | Operations and Engineering Users |
| Power Source A | Process Controllers and Server or Operator Layer A |
| Power Source B | Process Controllers and Server or Operator Layer B |
| Common risks: cabinet, route, room, cooling, time source, configuration, maintenance | Process Controllers, Server or Operator Layer A, and Server or Operator Layer B |
The table illustrates paths, not a universal design. Physical separation, independent power, network diversity, environmental controls, and configuration governance must be verified for the actual plant.
Redundant DCS Controllers
Redundant DCS controllers use an active controller and a standby controller, or an equivalent paired arrangement, to continue control when the active unit fails. Depending on the platform, the pair may synchronize application data, process state, diagnostics, and configuration. The transfer may be automatic, manual, bumpless, or controlled by a defined fault policy.
How Controller Failover Works
A controller pair normally exchanges health and synchronization information. When the active controller is declared unavailable, the standby controller assumes the defined role and continues from the available synchronized state. The important engineering questions are whether the standby has current logic and data, how I/O ownership changes, what outputs do during transfer, how communication clients react, and how operators are informed.
A DCS failover test should not stop at observing a “standby active” indication. It should verify process behavior, controller status, alarms, sequence execution, I/O updates, operator visibility, event timestamps, and recovery to a healthy pair. Test the failure modes relevant to the architecture, including controller power loss, communication loss, synchronization loss, and planned maintenance transfer.
Controller Redundancy Limitations
Controller redundancy does not eliminate risks created by shared I/O networks, common power, identical configuration defects, unsuitable environmental conditions, or a faulty engineering change copied to both controllers. If both units depend on one cabinet fan, one network route, or one time source, that dependency belongs in the failure-domain analysis. Redundant controllers also do not replace a separate safety instrumented function when the process requires one.
DCS Server Redundancy
DCS server redundancy may cover operator, engineering, historian, application, alarm, or other server roles, depending on the platform. A standby server may provide service continuity, data replication, client reconnection, or a recovery target. The design must specify which services are redundant and which dependencies remain common.
Review server identity, databases, storage, licensing or entitlement conditions, time synchronization, backup repositories, domain or authentication dependencies, antivirus and patch procedures, virtual infrastructure if used, and client behavior after failover. A second server in the same rack may not protect against rack power loss, cooling failure, physical damage, or a shared network switch.
Server failover testing should confirm service availability, client reconnection, alarm and event continuity, historian data behavior, engineering access, time alignment, and restoration of the failed service. Owners should request test records that show the date, preconditions, injected failure, observed behavior, alarms, data checks, recovery steps, exceptions, and responsible approvals.
DCS Network Redundancy
DCS network redundancy uses separate paths, interfaces, switches, rings, or routing arrangements to reduce the effect of a network component or path failure. The paths must be physically and logically reviewed. Two cables routed through the same tray, two switches powered from one source, or two links passing through one unmanaged dependency may not provide the intended independence.
Network redundancy should be evaluated for controller communications, server and client networks, engineering access, field networks, time services, alarm paths, and interfaces to SCADA or other systems. Confirm the behavior when one link, switch, route, interface, or power source is lost. A network-path failover can be technically successful while still creating a brief process disturbance, alarm burst, stale data condition, or operator confusion.
The design should define network health monitoring, alarm priorities, recovery time expectations, spare strategy, maintenance isolation, and configuration backup. A SCADA and HMI systems review can help examine how network degradation appears to operators and whether diagnostic information supports safe decisions.
Power and Environmental Redundancy
Power-supply redundancy is often overlooked because duplicated supplies may still share an upstream feeder, distribution board, UPS, battery system, fuse, or cabinet connection. Map the power path from source to load and identify which components are actually independent. Confirm load sharing, alarm behavior, battery autonomy where applicable, transfer response, and maintenance isolation.
Environmental resilience also affects availability. Redundant controllers or servers can fail together if both are exposed to excessive heat, dust, moisture, vibration, poor cooling, or a common room incident. Review cabinet location, cooling, fire protection, access, grounding, electromagnetic conditions, and physical separation. The objective is not to multiply equipment without purpose; it is to reduce credible common-cause failures.
DCS Availability vs Safety Integrity
Availability describes the ability of a system or function to remain operational or recover within a defined time. Safety integrity concerns the likelihood that a safety function performs correctly when required and is governed by a safety lifecycle and applicable standards. A redundant DCS may improve control availability, but it is not automatically a safety-rated system and should not be presented as a substitute for an approved safety instrumented architecture.
Functional-safety standards address lifecycle requirements for electrical, electronic, and programmable electronic safety-related systems.[2] The plant should therefore keep the control-system availability case separate from the safety lifecycle, hazard analysis, safety requirements specification, proof testing, and functional-safety validation. Where safety and basic control systems exchange information, the interface and failure behavior must be assessed by the responsible safety and control engineers.
Redundancy Assessment Checklist
Use this checklist during design review, brownfield assessment, or periodic reliability verification.
| Assessment Area | Evidence or Questions to Review |
|---|---|
| Failure coverage | Which single failures are covered, and which common-cause failures remain? |
| Controller pair | Are logic, process state, diagnostics, and I/O ownership synchronized and verified? |
| Server services | Which services fail over, how do clients reconnect, and what data can be lost or delayed? |
| Network paths | Are routes, switches, interfaces, trays, rooms, and power sources genuinely independent? |
| Power supplies | Do redundant supplies have independent upstream sources and tested alarm behavior? |
| Environment | Can heat, dust, moisture, fire, vibration, or access restrictions affect both sides? |
| Maintenance | Can one side be isolated, updated, or repaired while the other remains approved and healthy? |
| Configuration | Are backups, versions, changes, time sources, and recovery procedures controlled? |
| Testing | Are failover, degraded operation, recovery, alarms, and return-to-redundant-state tests documented? |
The assessment should identify residual risk rather than simply label the system “redundant.”
DCS Failover Test Checklist
Owners should request commissioning and periodic test evidence that includes:
- Test basis: Approved drawings, cause-and-effect or control narratives, architecture, acceptance criteria, and safety boundaries.
- Pre-test condition: Healthy active and standby units, synchronized configurations, valid backups, normal alarms, and recorded process state.
- Failure injection: The specific controller, server, network, or power failure introduced under an approved procedure.
- Switchover observation: Transfer indication, control continuity, I/O behavior, alarms, timestamps, operator display, and expected degraded modes.
- Functional verification: Control loops, sequences, interlocks, historian or event data, communications, and operator commands checked after transfer.
- Recovery: Failed equipment restored, resynchronized, returned to standby, and verified without introducing an unapproved configuration.
- Evidence package: Date, participants by role, instruments or tools used, screenshots or logs where appropriate, exceptions, corrective actions, and approval status.
A test that proves only that a standby light turns on is not enough to demonstrate operational failover.
Common DCS Redundancy Design Mistakes
A common mistake is duplicating equipment without separating the failure domain. Other failures include sharing one power source, network switch, cabinet, cable route, cooling system, time source, storage array, or maintenance procedure. Teams may also overlook standby configuration drift, stale backups, unsupported firmware, untested client reconnection, and alarms that do not clearly identify the active or failed side.
Another mistake is treating automatic transfer as proof of availability. The plant must define acceptable disturbance, data behavior, operator workload, degraded control, and recovery time. Maintenance actions should be simulated or reviewed because a small missing interlock, incorrect isolation, or weak change-control step can turn a minor intervention into a process event.
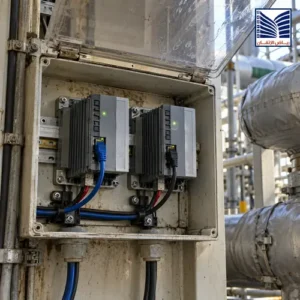
How Engineering Support Helps Review DCS Availability
An engineering assessment can document the installed architecture, map failure domains, review controller, server, network, and power redundancy, examine configuration and lifecycle dependencies, define failover scenarios, and prepare commissioning or periodic test procedures. It can also review alarm presentation, operator response, recovery documentation, spare strategy, cybersecurity boundaries, and the difference between availability objectives and safety requirements.
A structured review should deliver an architecture diagram, failure-mode register, dependency map, availability assumptions, test matrix, residual-risk list, and prioritized corrective actions. The recommendation should be based on verified plant data, approved vendor documentation, operating requirements, and evidence from testing—not on the presence of duplicate hardware alone.
Request a DCS Availability and Redundancy Architecture Review
Request a DCS availability and redundancy architecture review when a continuous process depends on controller pairs, server failover, redundant networks, dual power, or recovery infrastructure. The review can assess failure domains, switchover behavior, maintenance procedures, commissioning evidence, operator alarms, and lifecycle risks. To discuss the scope, use the contact technical support page.
The practical value of DCS redundancy comes from independent failure domains, known failover behavior, controlled maintenance, and repeatable test evidence. Without those controls, duplicate components may create confidence without equivalent protection.